DeepSeek V4.1 Flash (September)
Two DGX SparksretiredOn two DGX Sparks it decodes 81.9 tok/s. It gets 6 of 7 one-shot builds working. Ray tested it on 2026-10-17.
- Machine
- Two DGX Sparks: 2 × NVIDIA GB10, 2 × 128 GB unified memory, linked at 200 Gb/s
- Engine
- TensorFold Zig (Bertholomus AI)
- Weights
- EXL3 2.9 bpw community quant (Mia-AiLab)
- Recipe
- Tensor parallel over both Sparks, 1M context. Retired 2026-10-19 for 1017.
- Made by
- DeepSeek
- Size
- MoE
- Tested
- 2026-10-17
- Overall
- —
- Builds
- 857
- Knowledge
- —
- Speed
- 618
Scores out of 1,000. Overall is the mean of the other three; how each is scored.
Speed
- Decode speed
- 81.9 tok/s
- Decode, prose
- 71.9 tok/s
- Decode, Snake
- 91.9 tok/s
- First token
- 339 ms
- Prefill, 48k prompt
- —
- Tokens for the seven builds
- 225,888
- Time for the seven builds
- 45m 50s
Decode speed is the median of a prose prompt and a Snake game, one request at a time. Prefill is how fast it reads a 48,000-token codebase before it answers.
Accuracy
| Set | Correct | Score | Minutes |
|---|---|---|---|
| MMLU-Pro, 140 questions, thinking low | — | — | — |
| GSM8K, 100 problems, thinking low | — | — | — |
Builds
Run these pages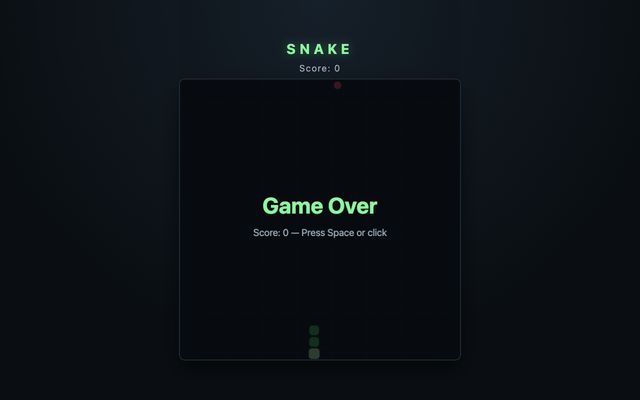
SnakeWorks
91.9 tok/s1m 22s7,546 tokens
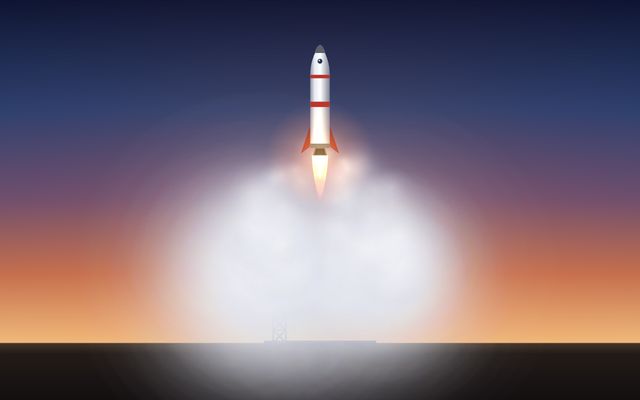
Rocket launchWorks
80.4 tok/s9m 57s47,975 tokens
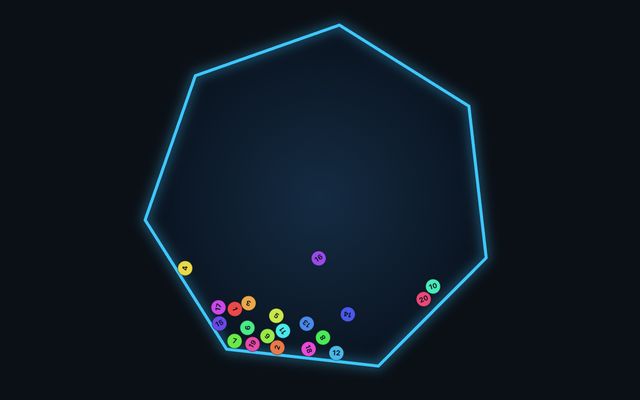
Heptagon ballsWorks
85.4 tok/s3m 21s17,167 tokens
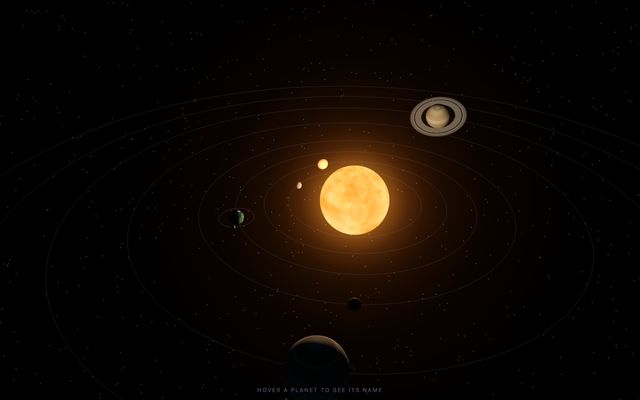
Solar systemWorks
84.3 tok/s5m 05s25,694 tokens
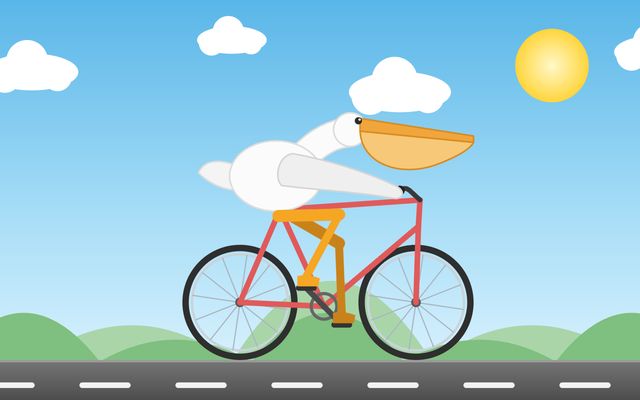
Pelican on a bicycleWorks
83.1 tok/s7m 08s35,514 tokens
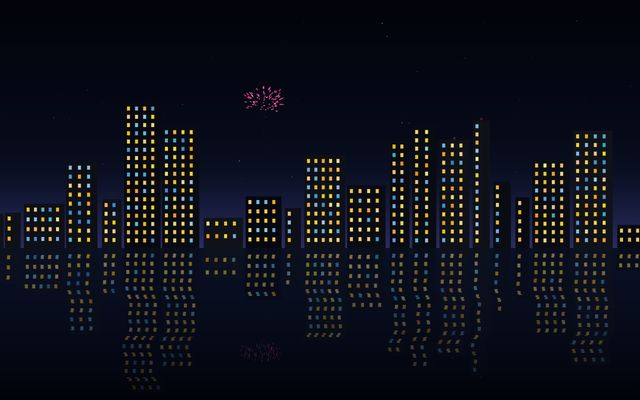
City fireworksWorks
82.0 tok/s5m 41s27,992 tokens
No page written
Gummy bearsNo page
80.7 tok/s13m 13s64,000 tokens
No page: it was still writing at this run’s 64,000-token cap. The build was retired before the 262,144-token rerun that 1017 got.
Run local models in Ownlight
Ownlight connects the model servers you already run, like Ollama, LM Studio, Unsloth Studio, llama-swap or Model Deck, and starts Claude Code or Codex on a local model beside your cloud agents. Local is part of Free.
Every step
Decode speed, time to first token, prefill speed, output tokens and total time for each prompt in the suite.
| Test | Decode tok/s | First token | Prefill tok/s | Output tokens | Total time | Run |
|---|---|---|---|---|---|---|
| Prose (speed) | 71.9 | 339 ms | — | 2,209 | 31.1 s | 775 |
| Snake | 91.9 | 603 ms | — | 7,546 | 1m 22s | 741 |
| Rocket launch | 80.4 | 838 ms | — | 47,975 | 9m 57s | 795 |
| Heptagon balls | 85.4 | 424 ms | — | 17,167 | 3m 21s | 793 |
| Solar system | 84.3 | 402 ms | — | 25,694 | 5m 05s | 796 |
| Pelican on a bicycle | 83.1 | 352 ms | — | 35,514 | 7m 08s | 794 |
| City fireworks | 82.0 | 409 ms | — | 27,992 | 5m 41s | 792 |
| Gummy bears | 80.7 | 563 ms | — | 64,000 | 13m 13s | 784 |
More models on the bench
- Qwen 3.8 27B on one RTX 5090, 189.2 tok/s
- Qwen 3.8 27B on one DGX Spark, 31.8 tok/s
- Nemotron 3.5 Super on one DGX Spark, 46.0 tok/s
- Qwen 3.8 Flash Next on one DGX Spark, 66.7 tok/s
- DeepSeek V4.1 Flash 1017 on two DGX Sparks, 78.6 tok/s
- GLM 5.3 Flash (uncensored) on two DGX Sparks, 55.6 tok/s
Updated 2026-10-20 16:39.