Qwen 3.8 27B
One DGX SparkOn one DGX Spark it decodes 31.8 tok/s and reads a 48,000-token codebase at 1,413 tok/s. It answers 82.1% of MMLU-Pro and gets 5 of 7 one-shot builds working. Ray tested it on 2026-10-19.
- Machine
- One DGX Spark: NVIDIA GB10, 128 GB unified memory
- Engine
- SGLang
- Weights
- NVFP4, official weights
- Recipe
- Ownlight’s tuned launcher, DFlash2 drafts
- Made by
- Alibaba Qwen
- Size
- 27B dense
- Tested
- 2026-10-19
- Asked who made it
- “I was developed by Alibaba Group’s Tongyi Lab.”
- Overall
- 649
- Builds
- 786
- Knowledge
- 821
- Speed
- 340
Scores out of 1,000. Overall is the mean of the other three; how each is scored.
Speed
- Decode speed
- 31.8 tok/s
- Decode, prose
- 25.7 tok/s
- Decode, Snake
- 37.9 tok/s
- First token
- 450 ms
- Prefill, 48k prompt
- 1,413 tok/s
- Tokens for the seven builds
- 259,165
- Time for the seven builds
- 2h 23m
Decode speed is the median of a prose prompt and a Snake game, one request at a time. Prefill is how fast it reads a 48,000-token codebase before it answers.
Accuracy
| Set | Correct | Score | Minutes |
|---|---|---|---|
| MMLU-Pro, 140 questions, thinking low | 115 of 140 | 82.1% | 11.8 |
| GSM8K, 100 problems, thinking off | 97 of 100 | 97.0% | 2.5 |
Builds
Run these pages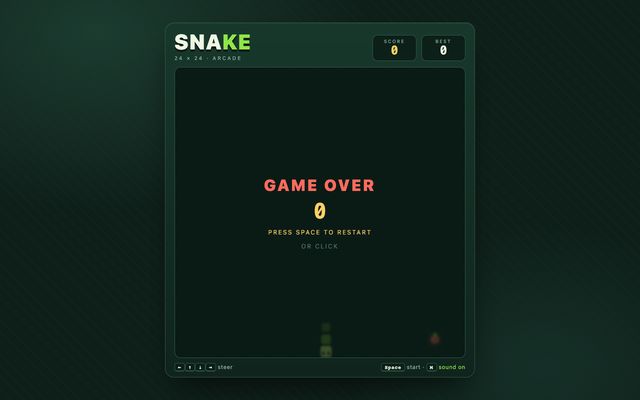
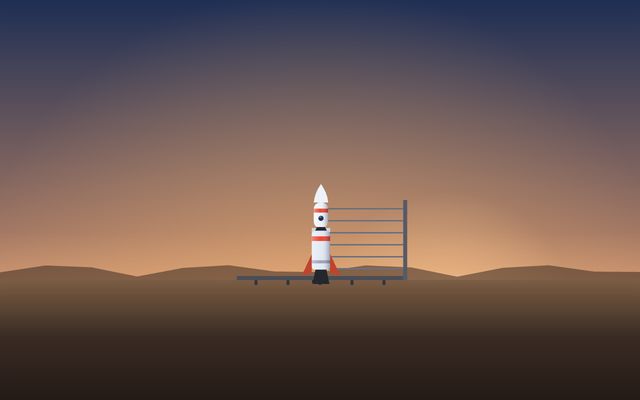
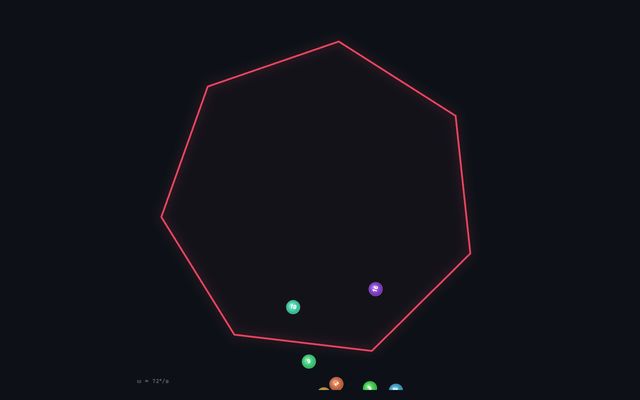
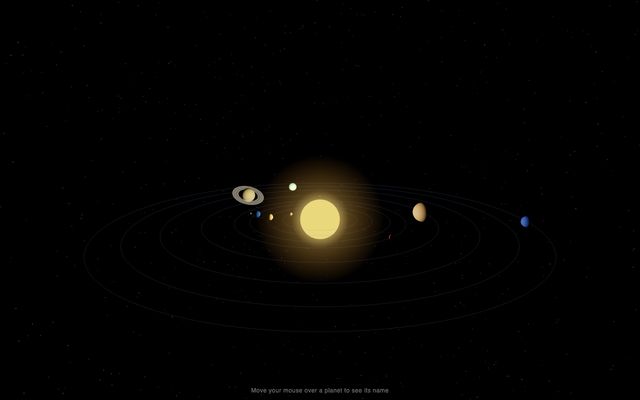
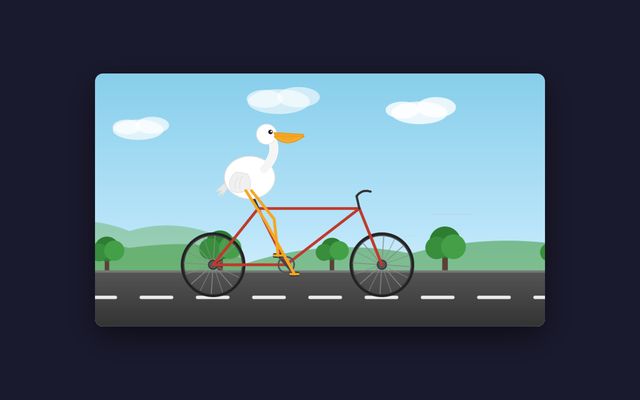
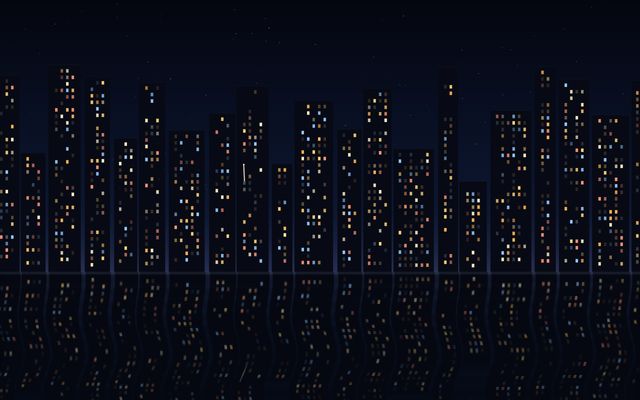
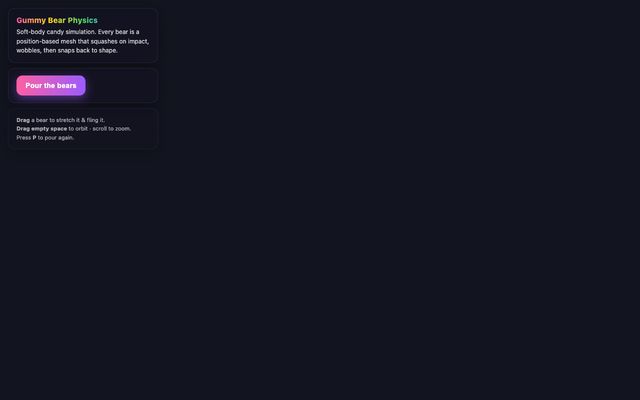
Run local models in Ownlight
Ownlight connects the model servers you already run, like Ollama, LM Studio, Unsloth Studio, llama-swap or Model Deck, and starts Claude Code or Codex on a local model beside your cloud agents. Local is part of Free.
Every step
Decode speed, time to first token, prefill speed, output tokens and total time for each prompt in the suite.
| Test | Decode tok/s | First token | Prefill tok/s | Output tokens | Total time | Run |
|---|---|---|---|---|---|---|
| Prose (speed) | 25.7 | 450 ms | — | 956 | 37.7 s | 860 |
| Snake | 37.9 | 171 ms | — | 23,400 | 10m 17s | 866 |
| Read a 48k-token codebase | 30.6 | 32.5 s | 1,413 | 695 | 55.2 s | 867 |
| Who made you? | 57.3 | 143 ms | — | 47 | 960 ms | 868 |
| Rocket launch | 30.5 | 164 ms | — | 61,637 | 33m 43s | 873 |
| Heptagon balls | 47.9 | 177 ms | — | 8,290 | 2m 53s | 874 |
| Solar system | 35.4 | 175 ms | — | 10,270 | 4m 50s | 875 |
| Pelican on a bicycle | 49.6 | 162 ms | — | 11,388 | 3m 49s | 876 |
| City fireworks | 29.7 | 167 ms | — | 12,204 | 6m 51s | 877 |
| Gummy bears | 27.2 | 188 ms | — | 131,976 | 1h 20m | 886 |
Other runs of Qwen 3.8 27B
| Machine | Decode tok/s | Prose | Snake | Engine and weights |
|---|---|---|---|---|
| One RTX 5090 | 189.2 | 169.1 | 209.2 | NInfer, NVFP4, official weights |
| Mac Studio M3 Ultra | 47.0 | 47.0 | — | llama.cpp, Q4_0 + DFlash2 drafts |
| One DGX Spark | 12.4 | 12.4 | 12.4 | SGLang NVFP4, no draft model |
More models on the bench
- Qwen 3.8 27B on one RTX 5090, 189.2 tok/s
- Nemotron 3.5 Super on one DGX Spark, 46.0 tok/s
- Qwen 3.8 Flash Next on one DGX Spark, 66.7 tok/s
- DeepSeek V4.1 Flash 1017 on two DGX Sparks, 78.6 tok/s
- GLM 5.3 Flash (uncensored) on two DGX Sparks, 55.6 tok/s
- DeepSeek V4.1 Flash (September) on two DGX Sparks, 81.9 tok/s, retired
Updated 2026-10-20 16:39.